Beyond the Prompt: Why Context Engineering Is the Key to Enterprise-Grade AI
The real challenge isn't the AI's intelligence; it's the AI's context. Why context engineering, not prompting, decides whether enterprise AI works.
We've all had our "wow" moment with Generative AI. A perfectly composed email. A complex concept explained in seconds. The sheer fluency of these models has captured executive imagination across every industry.
But when those same executives try to bring this power into their organizations, the "wow" fades fast.
"Why can't it answer a simple question about our Q3 sales performance?"
"It just gave a customer an answer based on an outdated return policy."
"It hallucinated a product feature we don't even offer."
The issue isn't the AI's intelligence. It's the AI's context. Public models were trained on the public internet -- a vast but generic dataset. Your business runs on proprietary data: your CRM records, your internal wikis, your compliance documentation, your customer history. The failure to bridge this gap is the single biggest blocker to enterprise AI success.
The discipline that has grown up around this gap now has a name: context engineering. Prompt engineering asks how to phrase a request. Context engineering asks what the model should be looking at when it answers, where that material comes from, who is allowed to see it, and what it should remember from the last turn. It is the difference between wording a question well and building the desk the question gets answered at.
From Prompt Engineering to Context Architecture
Many organizations start their AI journey by obsessing over prompt engineering. And while crafting good prompts is a useful tactical skill, it is not a strategy. You cannot "prompt" an AI into recalling your last decade of financial performance, understanding your unique supply chain constraints, or distinguishing between an active contract and an archived one.
The real strategic work is building a system that can securely, accurately, and dynamically inject your proprietary information into the AI's awareness at the exact moment it's needed.
The C-suite conversation must shift from "Which model should we use?" to "How will we manage our context?" This is not just a technical problem for the data team. It is a core business strategy that involves security, governance, data architecture, and workflow design across the entire organization.
What is "Enterprise Context"? Three Layers That Matter
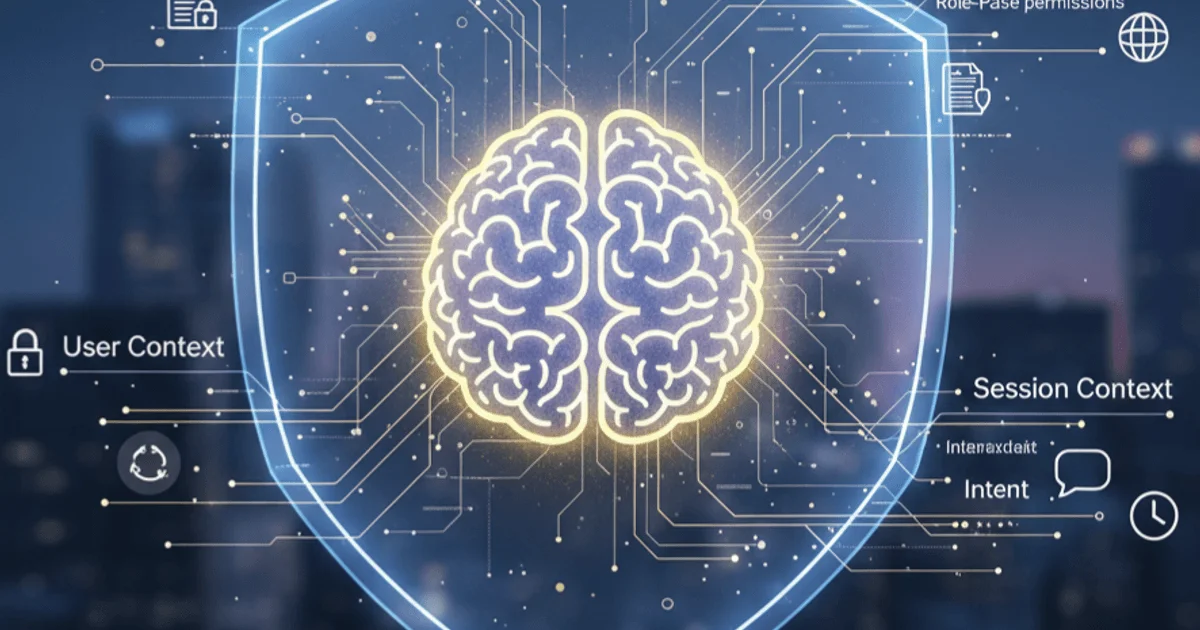
To make use of AI, you need to think about context not as a single concept but as three distinct layers, each with its own challenges.
Proprietary Data -- This is the foundation. Financial reports, CRM records, product roadmaps, R&D documents, internal wikis, HR policies, customer support histories. This is also your most sensitive asset. If it's not managed properly, the AI either can't use it or, worse, it leaks. A 2025 McKinsey survey found that 88% of organizations are now using AI in at least one business function, but data governance remains the number-one blocker for moving from pilot to production.
User Context -- Information about the person interacting with the AI. Is this a Senior VP of Sales asking about the global pipeline, or a new sales rep who should only see their own accounts? The AI must understand roles, permissions, and intent. Without user context, you get either security vulnerabilities (a junior employee accessing executive data) or irrelevant responses (a VP getting entry-level information). This is where your Identity and Access Management (IAM) infrastructure meets your AI stack.
Session Context -- The AI's short-term memory within a conversation. When someone asks "Show me our top 10 clients" and follows up with "Email the reps for the top 3," the AI needs to remember what "the top 3" refers to. A failure in session context is what makes most enterprise chatbots feel robotic and forces users to repeat themselves constantly -- which is also why adoption collapses.
The Architecture: How RAG Actually Works in Production
The initial impulse for many organizations is to fine-tune a foundation model on all their proprietary data. Fine-tuning has its place, but it is slow, expensive, and creates a static snapshot of your company that is outdated the moment you finish. Your business is dynamic; your AI needs to be too.
The modern approach is Retrieval-Augmented Generation (RAG) -- an architectural pattern where, instead of trying to train the AI to memorize every document your company has ever produced, you give it the ability to look up the exact right information from your secure, live data sources before generating a response.
Here is what a production RAG system actually looks like under the hood:
1. Ingestion and Chunking
Your documents (PDFs, Confluence pages, Salesforce records, Slack threads) get processed and split into chunks. This is not trivial. Fixed-size chunking (splitting every 500 tokens) is simple but ignores semantic boundaries. Semantic chunking -- where you embed each sentence, compare consecutive embeddings, and split where similarity drops -- can improve retrieval recall by up to 9% according to recent benchmarks. For most teams, recursive text splitting at 400-512 tokens with 10-20% overlap is a strong default that balances accuracy with computational cost.
2. Embedding and Vector Storage
Each chunk gets converted into a vector embedding, a numerical representation of its meaning, and stored in a vector database. This layer has matured to the point where the choice of database is rarely the bottleneck. Managed services such as Pinecone and open engines such as Milvus, Weaviate, and Vespa all handle enterprise volumes, and most now offer hybrid search that combines keyword matching with vector similarity, which consistently beats either method alone.
3. Retrieval and Generation
When a user asks a question, the system embeds that query, searches the vector database for semantically similar chunks, assembles the most relevant context, and passes it to the language model along with the question. The model generates its answer grounded in your actual data, not its training data.
For interactive enterprise use you are targeting under 3 to 5 seconds end to end. An untuned pipeline blows past that easily.
4. Beyond Basic RAG
The RAG landscape is evolving rapidly. Graph RAG overlays knowledge graphs on top of vector retrieval, letting the system traverse relationships between entities (e.g., understanding that a customer complaint connects to a specific product version connects to a specific engineering team). Agentic RAG adds a reasoning layer: instead of a single retrieval pass, an AI agent decides if its initial results are good enough, formulates more specific queries, reflects on quality, and dynamically constructs the right context. Think of it as the difference between a keyword search and a research analyst.
Why This Is a Business Strategy, Not a Tech Project
I've spent 30 years watching enterprise technology adoption cycles. The pattern is always the same: the companies that win are not the ones with the best technology -- they are the ones with the best integration strategy.
Context engineering is no different. The technical components (vector databases, embedding models, retrieval pipelines) are increasingly commoditized. The hard part is the organizational work:
- Data governance: Which data sources should the AI access? Who owns data quality? How do you handle PII and compliance requirements?
- Access control: How do you ensure the AI respects your existing role-based permissions when it retrieves information?
- Change management: Your data is not static. Products change, policies update, employees come and go. Your RAG pipeline needs continuous ingestion and re-indexing.
- Measurement: How do you know the system is working? You need retrieval precision metrics, hallucination detection, user satisfaction tracking, and feedback loops.
This is where Deloitte's 2026 State of AI survey is instructive: 85% of companies expect to customize AI agents to fit their unique business needs, but only 21% report having a mature governance model. That gap -- between ambition and governance readiness -- is where most enterprise AI initiatives stall.
Context Is Your Competitive Moat
Public AI models are becoming powerful, accessible commodities. Any competitor can access the same foundation models you can. Your only defensible, long-term advantage is your unique business context: your proprietary data, your customer relationships, your institutional knowledge, your operational history.
The systems you build to securely manage this context and feed it to your AI applications will define your competitive position for the next decade. Not which model you picked. Not how clever your prompts are. Whether your AI can actually reason over your data, in real time, with proper guardrails.
Building an AI strategy is building a context strategy. The organizations that understand this distinction -- and invest in the architecture, governance, and data infrastructure to back it up -- will be the ones that move from impressive demos to measurable enterprise value.